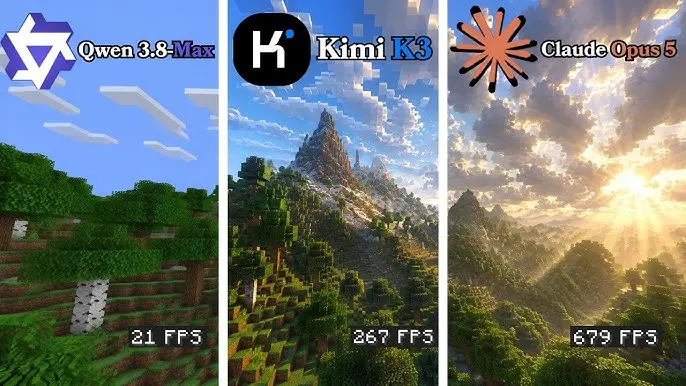
Credit: Made by VentureBeat with GeminiAlibaba released Qwen 3.8-Max this week and marketed the preview as second only to Claude Fable 5 (their launch-day table was more equivocal: the model leads on one of 12 coding-agent rows). But an independent harness came close to the opposite conclusion: a benchmark run, apparently using the Preview version, put Qwen 3.8-Max’s best effort setting mid-pack, and its default setting last.Both results are real and defensible. The gap between them is about token and time budgets, and that matters because those figures aren’t usually headline numbers. Alibaba’s footnotes give its coding numbers a five-hour timeout, and up to 12 hours per run on PaperBench. The independent harness, VulcanBench, allowed between…
Qwen 3.8-Max and Claude Opus 5 show why raw benchmark scores don’t predict the bill
 Continue reading at
VentureBeat
venturebeat.com
Advertisement