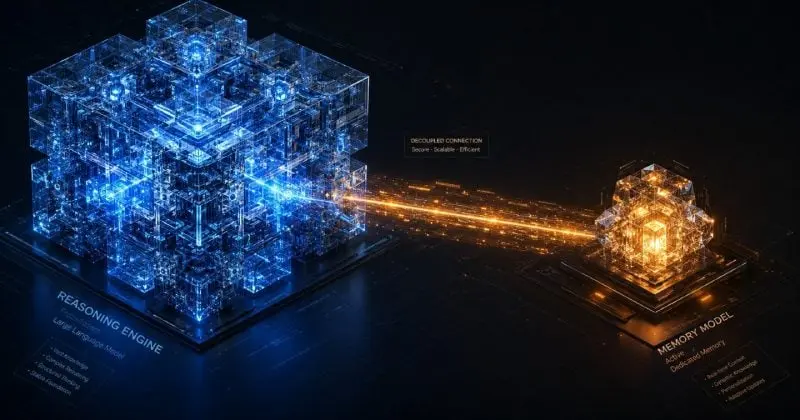
Image credit: VentureBeat with ChatGPTEnabling LLMs to acquire new knowledge after training remains a major hurdle for enterprise AI — current solutions are either too expensive, too slow, or constrained by context window limits.MeMo, a framework from researchers at multiple universities, encodes new knowledge into a dedicated smaller memory model that operates separately from the main LLM.The modular architecture works with both open- and closed-source models and sidesteps the complexity of RAG pipelines and full model retraining.Experiments show that MeMo handles complex queries reliably even when retrieval pipelines are noisy. It avoids the catastrophic forgetting associated with direct fine-tuning and provides a cost-effective pathway for…
MIT’s MeMo lets teams swap in a better LLM without retraining — and performance jumps 26%
 Continue reading at
VentureBeat
venturebeat.com
Advertisement